III · the course — follow along, don't just read
The course. Start your timer.
Open a terminal next to this page (Mac: press ⌘ + Space, type "Terminal", hit enter — that's the whole setup). Every module below is: do this → here's exactly what you'll see → checkpoint. If you can copy and paste, you can finish this course.
Not a terminal person at all? Modules 3 and 4 work in the chat at kimi.com too — I'll flag it when they do.
Module 1 · 0:00–0:10 — Get K3 (check what you already own first)
What you'll have at the end: a working K3 connection, very possibly for free.
K3 has two doors, and most people don't realise they're already holding a key to door one.
Step 1 — find your Kimi key. If you have the Kimi coding plan (the one that powers Kimi Code), log into kimi.com → settings → API keys. It starts with sk-kimi-. Copy it.
Step 2 — ask the endpoint what your plan serves. Paste this into your terminal (swap in your key):
export KIMI_API_KEY="sk-kimi-your-key-here"
curl -s https://api.kimi.com/coding/v1/models -H "Authorization: Bearer $KIMI_API_KEY"
Here's what you'll see — a JSON list of models. On launch day mine came back with three, and the one that matters is just two characters:
{"data":[
  {"id":"kimi-for-coding", ...},
  {"id":"kimi-for-coding-highspeed", ...},
  {"id":"k3", ...}    ← this line means the flagship is on your existing plan
]}
See k3 in that list? You're done paying. That's a 2.5-trillion-parameter frontier model riding a subscription you already own.
No Kimi plan? Door two. Grab a key at openrouter.ai — the model slug is moonshotai/kimi-k3, $3 per million input tokens, and everything in this course works the same way (endpoint https://openrouter.ai/api/v1 instead).
If it breaks:the two errors everyone hits in module 1
401 Unauthorized → your key is fine but it's the wrong KIND of key. Kimi has two: platform keys and coding-plan keys. K3-for-free needs the coding-plan key on the /coding/v1 endpoint.
404 or an empty list → you're on api.moonshot.ai (the platform endpoint). Point at api.kimi.com/coding/v1 — same key, different door.
✅ Checkpoint: your terminal shows a models list containing k3 (or your OpenRouter key accepts the slug). That's minute ten.
Module 2 · 0:10–0:20 — First words (and the trap that catches everyone)
What you'll have at the end: a real conversation with K3 — and proof of what's actually answering.
Step 1 — say hello properly. This is the exact request shape you'll use all course. Two settings matter and I'll explain both the moment you see them:
curl -s https://api.kimi.com/coding/v1/chat/completions \
  -H "Authorization: Bearer $KIMI_API_KEY" -H "Content-Type: application/json" \
  -d '{"model":"k3",
       "messages":[{"role":"user","content":"What model are you?"}],
       "max_tokens":16000}'
Why max_tokens: 16000 and not 500? K3 is a reasoning model — it thinks before it answers, and the thinking spends your token budget. Set it low and the thinking eats everything: you get an empty answer and assume the model is broken. It isn't; it starved. I learned this the annoying way — my first SEO audit came back blank at 4,000. 16,000 is the floor; long builds want 48,000.
And don't set temperature. The coding endpoint accepts exactly one value (1) and errors on anything else: invalid temperature: only 1 is allowed. Just leave it out.
Here's what you'll see — and here's the trap. K3 answers something like:
"I'm Kimi K2.7, an AI assistant from Moonshot AI..." ← the model, being wrong about itself
Ask a model what it is and it tells you what its training data remembers — models are the last to know their own names. The truth is in the response envelope, not the prose. Step 2 — read the envelope:
curl -s https://api.kimi.com/coding/v1/chat/completions \
  -H "Authorization: Bearer $KIMI_API_KEY" -H "Content-Type: application/json" \
  -d '{"model":"k3","messages":[{"role":"user","content":"hi"}],"max_tokens":16000}' \
  | python3 -c "import json,sys; print('served:', json.load(sys.stdin)['model'])"
Here's what you'll see:
served: k3 ← the endpoint's own receipt. This one can't lie.
✅ Checkpoint: served: k3 in your terminal. You now have a verification habit that transfers to every model you'll ever test.
Module 3 · 0:20–0:30 — Stretch the million-token memory
What you'll have at the end: proof, on your own documents, that the headline feature is real. (This one works at kimi.com too — paste instead of curl.)
The pitch is a one-million-token window — roughly 750,000 words in view at once. Spec sheets say that; needles prove it.
Step 1 — build a haystack. Take the longest documents you have and stack them into one file. On a Mac:
cat ~/Documents/project-docs/*.md > haystack.txt
wc -w haystack.txt     # aim for 50,000+ words — the bigger the better
Step 2 — bury a needle. Open the file and paste one invented line somewhere in the MIDDLE (the middle is where models forget):
The vault code is 7429 and the contact is Marcus Webb.
Step 3 — make it dig. Send the whole haystack with the question "What is the vault code and who is the contact?" — nothing else, no hints about position.
Here's what you'll see. My launch-day run: 162,000 tokens of noise, needle at line 4,321. K3 came back in 18 seconds:
The vault code is 7429 and the contact is Marcus Webb. ← exact, no "I think", no partial recall
What this means for your actual work: your whole codebase in one prompt. Your whole client-doc folder. A month of chat logs. "Summarise what we decided about pricing across all of this" becomes a real question.
✅ Checkpoint: exact recall of YOUR needle from YOUR haystack. If it misses, your haystack was probably under 10k words — too easy for the test to mean anything. Go bigger.
Module 4 · 0:30–0:40 — Build something you can touch
What you'll have at the end: a working artifact that didn't exist ten minutes ago. (Also works at kimi.com — same prompt, download the file it returns.)
Step 1 — pick the build closest to your business and use this exact prompt shape:
"Build a beautiful one-page website for [your business].
Dark elegant design, hero + services + contact section.
ONE self-contained HTML file — all CSS and JS inline. Return ONLY the HTML."
The two load-bearing phrases: "one self-contained HTML file" (so you get a thing that opens, not a folder of fragments) and "return ONLY the HTML" (so you don't have to fish code out of an essay).
Step 2 — start it, then walk away. Here's what nobody tells you about K3: it's SLOW on hard tasks, and that's a feature. My one-shot game took 13.4 minutes of thinking and produced 30,880 tokens of working code with zero errors. The wrong move is watching the cursor blink and assuming it died. Set max_tokens to 48000, start the request, make coffee.
Step 3 — save and open what comes back. Paste the output into a file called build.html, double-click it. Here's what you'll see — both of my module-4 runs, embedded live:
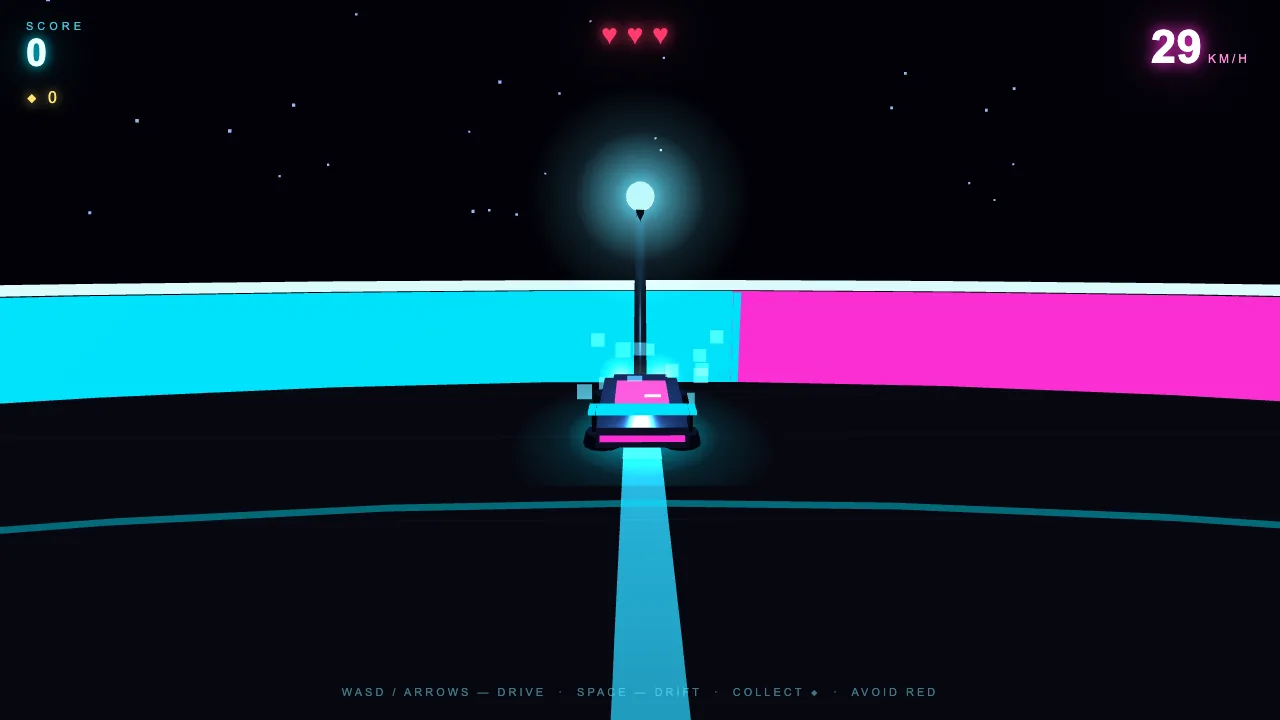
Run 1 — "build a complete 3D game, one file" (click to start, WASD to drive)
⛶ open full screen
Run 2 — the website prompt above, pointed at a luxury watch studio
⛶ open full screen
Both are the actual files K3 returned — playable and scrollable right here, not screenshots.
Step 4 — the round-two move. Don't accept draft one; steer it. I sent the game back with "add four hunter drones that chase the player, a hull bar, and redesign it Tron-style" — one follow-up, and the drones in that embed above are the result. Whatever your build is missing, ask for it in one specific sentence.
✅ Checkpoint: a file open in your browser doing what you asked — plus one steered improvement, so you've felt the edit loop, not just the magic trick.
Module 5 · 0:40–0:50 — Give it an agent job, not a chat
What you'll have at the end: K3 completing a multi-step job with a verifiable end state — the thing it's actually tuned for.
A chat answers you. An agent CHANGES something and proves it did. The difference is the job description — give it a task where success is checkable:
"Create a file called playbook.md containing a 300-word briefing on [your topic]
with 5 numbered steps. Write the file, VERIFY it exists on disk,
and report its exact size in bytes."
Run that through any agent runner you have (Kimi Code CLI, Hermes, Claude Code with the K3 endpoint — the runner matters less than the job shape). Here's what you'll see — my launch-day run, verbatim:
✓ Wrote k3-agent-demo.md
✓ Verified: file exists on disk
✓ Size: 2,119 bytes · 5 numbered steps present
The agent closed the loop — wrote, checked, reported. Nobody re-prompted it.
And when you're ready to see how far this goes: the same pattern, pointed at Blender through an MCP connection, produced this — a video the agent modelled, lit, animated, luminance-checked and rendered by itself:
Module 5 at full power: the agent's own MP4 — 150 frames, keyframed liftoff, tracked camera. It even measured its check-frames' brightness before committing to the final render. The full build story is in The Long-Haul Engine.
✅ Checkpoint: a job that ended in a verified artifact, not a paragraph of advice.
Module 6 · 0:50–1:00 — Wire it in as a slot, not a religion
What you'll have at the end: K3 living inside your daily stack as one switch among several.
Step 1 — give it a permanent seat. If you run Kimi Code, add an alias so k3 is one flag away — this exact block goes in ~/.kimi-code/config.toml:
[models."kimi-code/k3"]
provider = "managed:kimi-code"
model = "k3"
max_context_size = 1048576
display_name = "K3"
Running Hermes? Same idea, two commands: hermes profile create kimi-k3 --clone-from kimi-highspeed (then set its model to k3 and drop your key in the profile's .env), and hermes profile alias kimi-k3 so kimi-k3 -z "the job" --yolo dispatches it from anywhere.
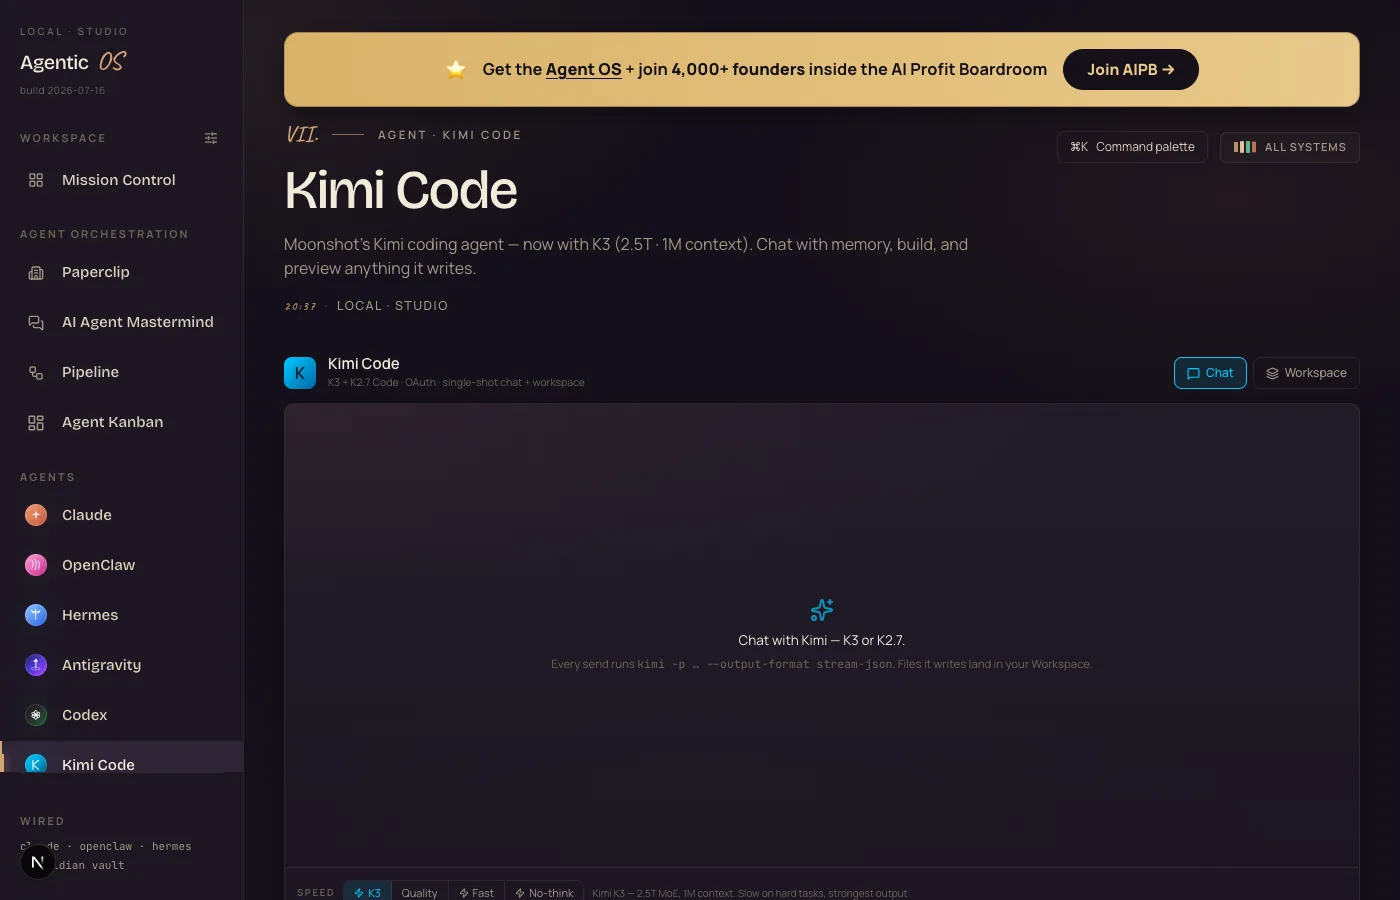
Here's what you'll see — mine, wired into the Agent OS dashboard the same afternoon:
K3 as one labelled toggle among four — next to the models it now competes with for every job.
Step 2 — decide its lanes. The operator move is routing, not religion. From a week of real use: K3 gets the MILLION-TOKEN jobs (whole-codebase questions, giant doc analysis) and the UNATTENDED jobs (agents that run twenty minutes and verify their own work). Your fast daily driver keeps the quick chats — K3 is too slow for those, and that's fine.
Step 3 — bench it on YOUR work. Take one real task you did this week, run it through K3 and through your current model, compare outputs side by side. That comparison — not launch-thread hype — decides what K3 does for you. (Want the full version of that method? The Frontier Shootout.)
✅ Checkpoint: K3 answers from inside your own stack, your old models still in their seats, and you know which jobs are K3's.
Time. You're an operator now — you've verified it, stretched it, built with it, run it as an agent, and given it a seat. That's the whole hour.
Reading about models is a hobby. Operating them is a skill.