JoinGemma 4 update · a frontier model, free on your Mac
The Limitless Local Machine™.
Google just shipped a big Gemma 4 update — and I wired the latest version straight into my Agent OS as the free local brain. No meter. No quota. No bill. It runs on my Mac with the internet off.
✦ Every cloud AI runs a meter · this one doesn't● gemma4:12b · live in my Agent OS
0
× faster with the new MTP drafters
$0
per token, per month, forever
0
K context window (gemma4:12b)
Straight from Google — read it + run it yourself ↓
"We're rolling out some big improvements to Gemma 4, fueled by incredible community feedback and contributions!"
— Google Gemma (@googlegemma) · Jul 15, 2026
The update · what actually shipped
Google keeps making the free one better
Here's what's going on. Gemma 4 is Google's open model — the one you download and own. This release rolls in the community-driven fixes plus the big one from this cycle: MTP drafters, which let the model draft its own next words ahead of time. Up to 3× faster — and that speedup landed in Ollama, the free tool that runs it on your Mac.
Why it matters for you: the free, private, offline model just got fast enough to feel like the paid cloud ones.
The July speedup, in plain words: it used to write one word at a time — now it drafts several ahead and checks them, finishing up to 3× faster.
✦
I · the problem
The Running Meter Problem.
Every AI you use has a meter on it.
Tokens. Quotas. Rate limits. Monthly plans.
Every question you ask, the meter ticks.
So you ration yourself. You save the "good" AI for the important stuff.
You hesitate before running the big job.
And when the wifi drops, or the service goes down, or the price goes up — your AI is gone.
You don't own it. You're renting it, by the word.
The Limitless Local Machine ends that.
Thinking it? "Local models are toys — the real power is in the cloud."
That was true two years ago. Gemma 4's 31B jumped from 20.8% to 89.2% on AIME — and the 12B running on my Mac writes, codes and reads images.
For the everyday 90% of work, the free local one is plenty. And it just got 3× faster.
II · how it works, in simple words
The whole brain lives on your machine.
Here's the mental model.
A cloud AI is a phone call: your question travels to someone else's computer, gets answered there, and the answer travels back. That's why there's a meter — you're using their machine.
A local model is different. You download the entire brain once — Gemma 4 12B is a 7.6GB file — and it runs on your own Mac's chip.
No call. No meter. Nothing leaves the machine.
Ask it once or ten thousand times — the cost is the same: nothing.
Unplug the internet and it keeps working, because there's nothing to call home to.
That's the whole trick. You stop renting intelligence by the word and start owning it.
Download the brain once, then every question stays on your machine. The meter reads zero forever.
✦
III · exactly how it works, step by step
What I did on my machine — copy it.
This is the literal install I ran, start to finish. Three commands and one line in a file.
1
Install Ollama — the free app that runs open models on a Mac. Download from ollama.com, drag to Applications, done.
2
Pull the latest Gemma 4. One command in Terminal: ollama pull gemma4:12b. That downloads the whole 7.6GB brain — the July release, MTP speedup included.
3
Test it.ollama run gemma4:12b and ask it anything. Mine answered on 100% GPU — the Mac's chip doing all the work, no cloud.
4
Pin it in the Agent OS. One line in the dashboard's .env.local: LOCAL_MODEL=gemma4:12b. Now the whole Local section — chat, voice builds, the kanban's local worker, the loop judge — runs on Gemma.
5
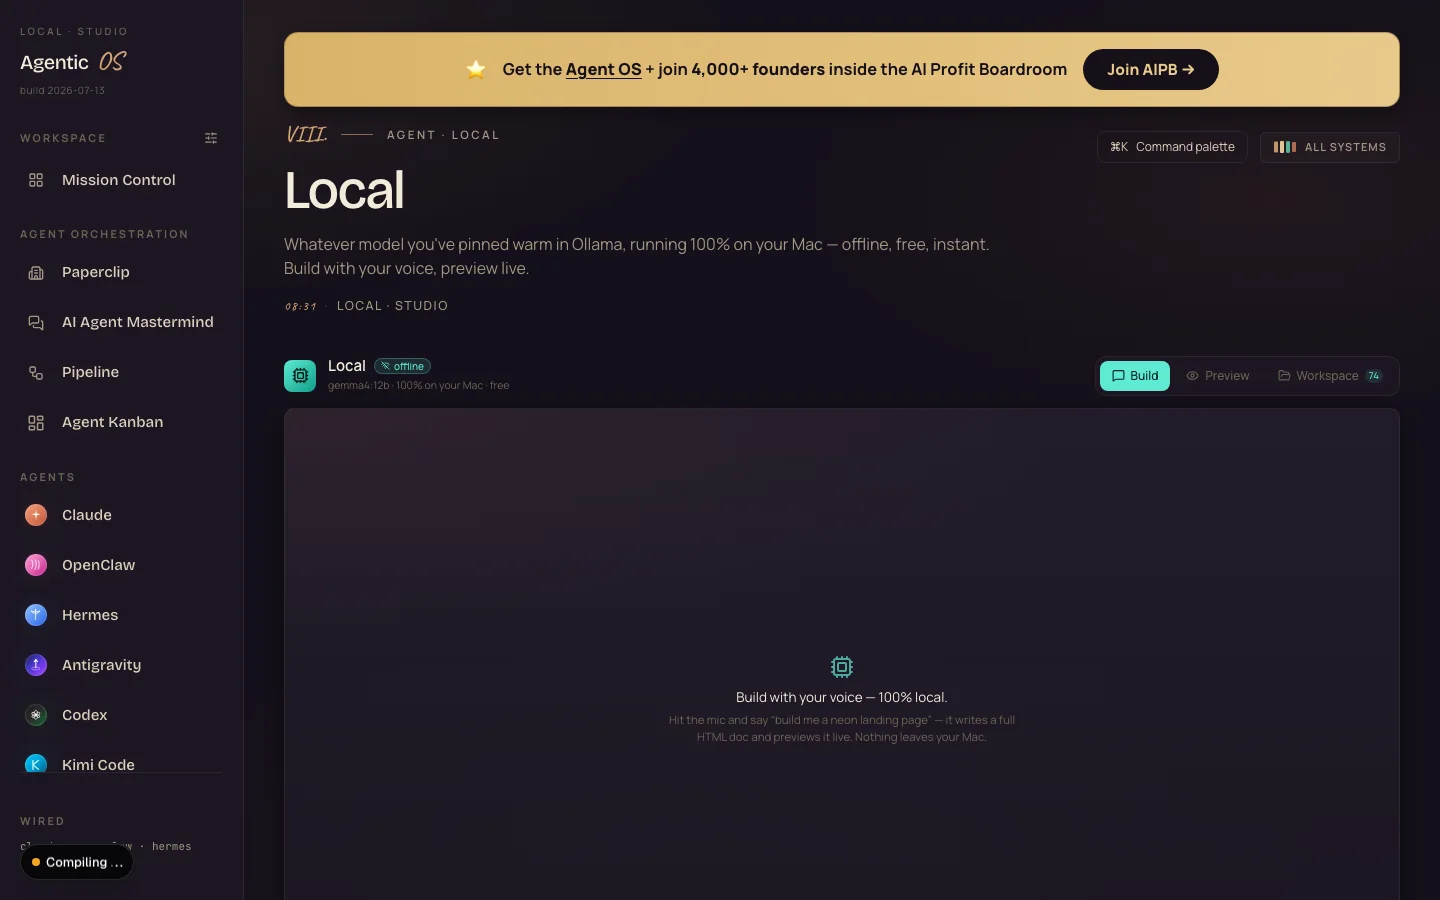
Verify. I opened the Local page and the header read gemma4:12b · 100% on your Mac · free — then streamed a live reply through the dashboard to prove it end to end.
6
Bonus: Gemma 4 12B needs ~8GB warm. The model it replaced needed 22GB. My Mac got 14GB of RAM back on the same job.
# the whole install, in full:
ollama pull gemma4:12b        # download the brain (7.6GB, once)
ollama run gemma4:12b         # talk to it — offline, free

# wire it into the Agent OS (one line in .env.local):
LOCAL_MODEL=gemma4:12b
So when someone asks "but what IS it?" — it's Google's open AI model, downloaded once as a file, running free on your own Mac's chip inside your Agent OS.
What you're looking at: my Local section right after the pin. The header is the proof — gemma4:12b · 100% on your Mac · free. Everything this page does (chat, voice builds, live preview) now runs on the new Gemma, offline.
✦
IV · old way vs new way
Renting AI vs owning it.
The old way · rented by the word
$/forever
Every question ticks a token meter
Rate limits kick in exactly when you're busiest
Your prompts travel to someone else's computer
Wifi down = AI gone
Price hike or model shutdown = your workflow breaks
You ration the "good" AI for special occasions
The Limitless Local Machine
$0/forever
No meter exists — ask it all day, every day
No rate limit, no quota, no cutoff
Nothing ever leaves your machine — fully private
Works on a plane with the wifi off
You own the weights — nobody can take them back
Every Google update (like this 3× one) is a free upgrade
Thinking it? "My Mac isn't powerful enough for this."
Gemma 4 comes in sizes. The 12B runs in ~8GB — fine on any Apple Silicon Mac with 16GB. There's a smaller default that runs on even less.
You don't need a monster machine. You need one command.
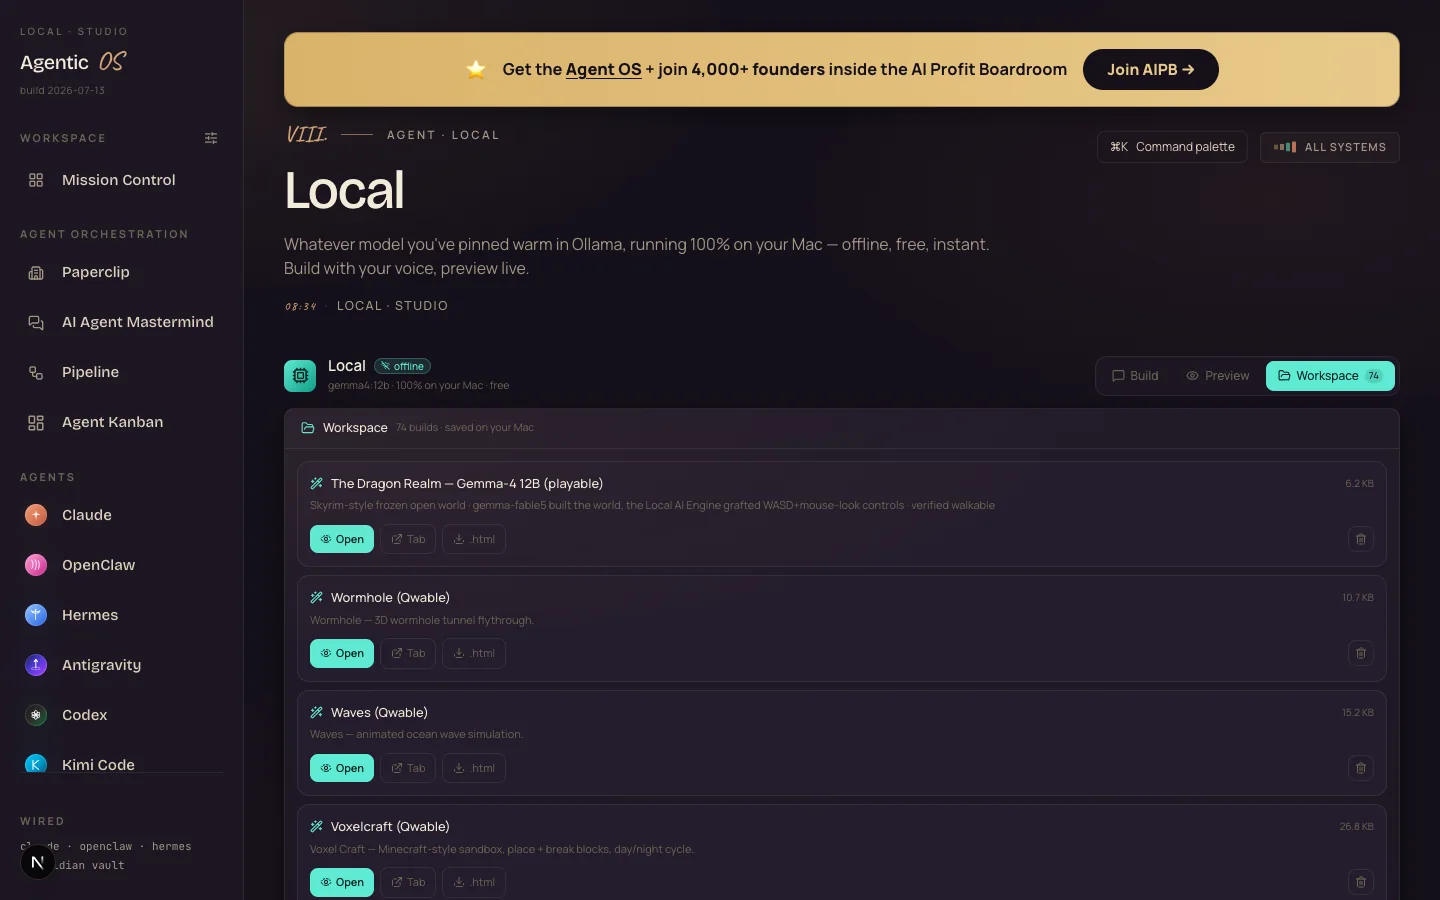
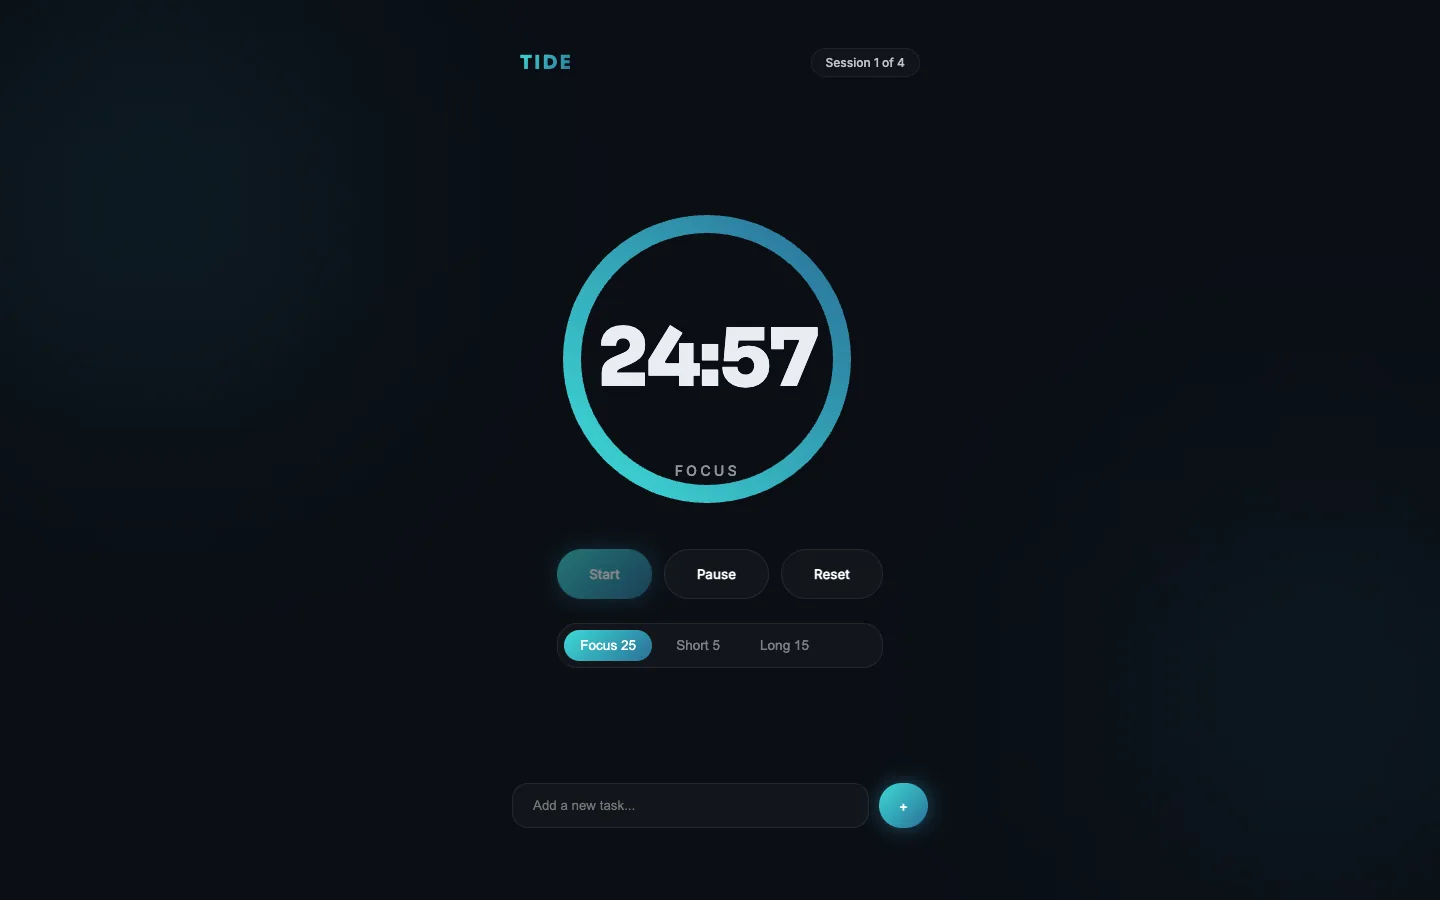
What you're looking at: the Local section's Workspace — 74 builds saved on my Mac, all made by local models at $0. Top of the list: a playable Skyrim-style game built by a Gemma-4 12B. This is what "limitless" looks like — you build without ever watching a meter.
✦
the proof · built by this exact model
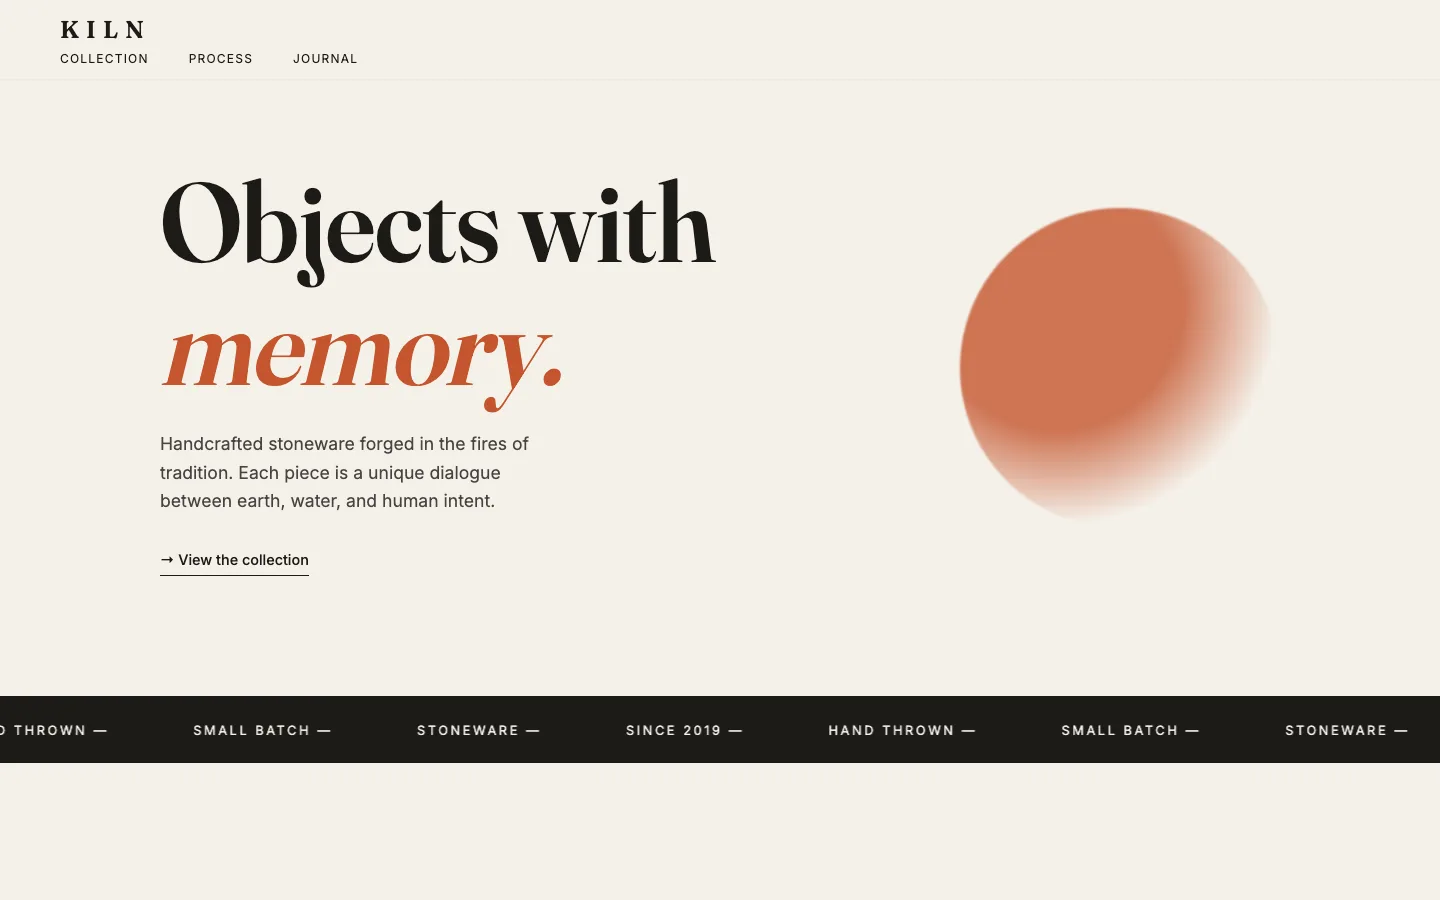
Three things Gemma 4 built right after I installed it.
Talk is cheap, so I put the machine to work.
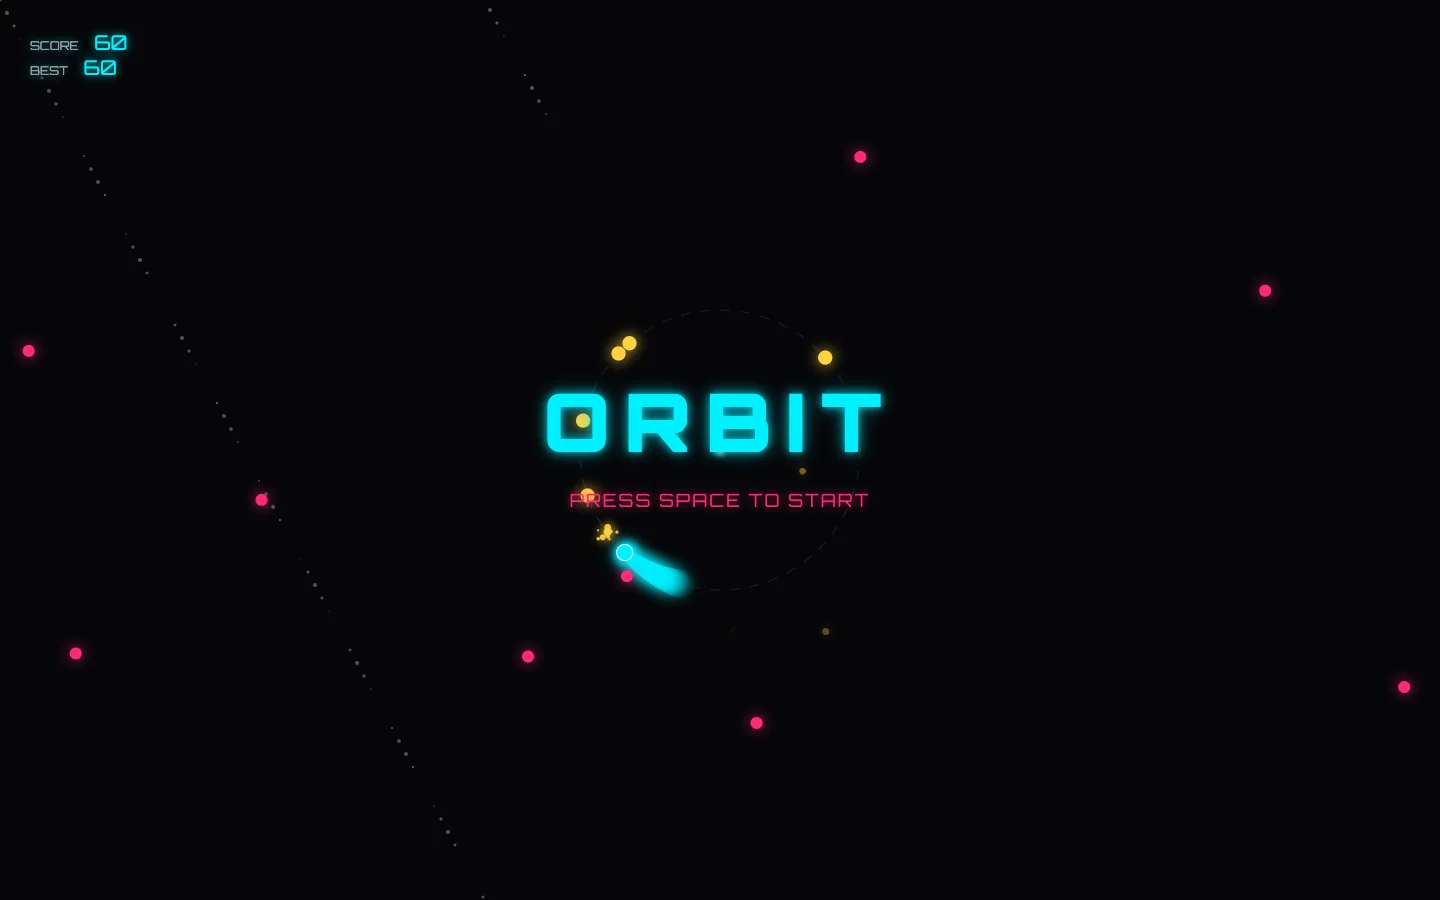
I gave gemma4:12b three briefs — a website, an app, and a game.
It wrote every line itself, on my Mac, offline, at $0.
All three worked first try — zero JavaScript errors, and the game scored 60 points in an automated playtest before I'd even opened it.
All three are single files Gemma wrote in one pass each, ~3 minutes apiece on my Mac. No cloud call, no token spent, nothing edited by hand.
Stop renting intelligence by the word. Own the machine.
V · the framework
The Limitless Local Machine™ — five layers.
The whole method, bottom to top. Layers i–iii get the brain onto your machine; layers iv–v are where it pays you back.
i.
Pull
One command downloads the whole brain: ollama pull gemma4:12b. 7.6GB, once, free. That file is yours forever.ollama.com · 2 minutes
ii.
Pin
One line — LOCAL_MODEL=gemma4:12b — locks it in as the Agent OS's local brain, so every local surface uses it and the label never lies..env.local · 1 line
iii.
Run
It runs 100% on your Mac's GPU. Offline, private, unmetered — and with the new MTP drafters, up to 3× faster than before.100% GPU · works offline
iv.
Build
The Local section rides it: chat, voice-to-build, live previews, the kanban's local worker, the loop judge. The everyday 90% of agent work, at zero cost.Agent OS · /local
v.
Limitless
No meter, no quota, no bill — and every Gemma update Google ships (like this one) makes your machine faster for free. It compounds without costing.$0 · forever
Pull → Pin → Run → Build → Limitless. Two commands and one line, then it pays you back forever.
✦
Skip the setup
Get the Limitless Local Machine built for you.
You can run the three commands above yourself. Or get the whole thing done, inside the Agent Operating System — Gemma 4 pinned as the local brain, plus every cloud agent I use, all sharing one dashboard and one memory.
The full Agent OS zip — the Local engine + Gemma 4 pre-wired
The local-model playbook: which size for which Mac, on video
Coaching calls where I set up your local machine with you
A room of 3,900+ operators running this exact stack
Token-efficiency tutorials — cut what you still spend to the bone
Get the Agent OS →Inside the AI Profit Boardroom · aiprofitboardroom.com
Thinking it? "Doesn't running the Agent OS burn a fortune in tokens?"
This guide is literally the answer. The everyday 90% runs on this free local model — zero tokens, nothing leaving your Mac. Free APIs slot in for more. And the heavy work drives the CLIs you already pay for — your Claude subscription already includes the Claude CLI, so you're not paying twice.
The Limitless Local Machine is the reason the token objection is dead.
✦
VI · why listen to me
This is my actual machine.
The screenshots above aren't a demo — that's my Agent OS, today, with Gemma 4 pinned and 74 local builds in the workspace. I run my business on this stack and film it daily.
0K YouTube subscribers
0+ members in AIPB
0builds by local models · $0
0K followers on X
Members run the same local stack on their own machines — real results, in their own words.
Wrong: "Free local models are way behind — I'd be settling."
Right: Gemma 4 31B went from 20.8% to 89.2% on AIME in one generation, and the July update made it up to 3× faster. The gap isn't what it was — for daily work, it's gone.
Wrong: "Setting up a local model is a weekend of pain."
Right: It's one app and one command: ollama pull gemma4:12b. Mine was answering questions in under ten minutes, and one more line wired it into the whole Agent OS.
Wrong: "I already pay for AI — a local model adds nothing."
Right: It's not instead of your paid AI — it's the free floor under it. Route the everyday 90% to the $0 machine and save the paid calls for the work that earns.
Don't take my word for it
158 pages of members — real businesses, real wins — running their AI without watching a meter.
Install Ollama, run ollama pull gemma4:12b, and ask it ten questions about your business. Feel the zero-meter difference.
Week 1 · Pin
Wire the Agent OS
Set LOCAL_MODEL=gemma4:12b so every local surface — chat, builds, kanban worker — runs on it.
Week 2 · Route
Move the 90%
Push drafts, summaries, classifying and everyday questions to the free machine. Watch your paid usage drop.
Week 3–4 · Compound
Ride the updates
Every Gemma release is a free upgrade to a machine you own. Update, re-pull, keep building at $0.
The meter reads zero. It always will.
Your move
Put a free frontier brain in your corner.
Grab the Agent Operating System inside the AI Profit Boardroom. The Limitless Local Machine — Ollama, Gemma 4, the Local engine, the voice builder — pre-wired next to every cloud agent I run, all on one dashboard with one shared memory.
The full zip. Pull → Pin → Run → Build, already done
Coaching calls where we set up your machine together
3,900+ members · daily tutorials · a member map for your city
The AI Profit Boardroom is where the actual Agent OS lives — the templates, the prompts, the daily rooms, the weekly walkthroughs. Same builds you read about here, taught hands-on inside.